Blog
Blog
Stories, how-tos and talk recaps from people running data on Kubernetes.
- All posts
- DoK Day at KubeCon NA 2021
- Announcement
- DoK Day at KubeCon EU 2022
- How To
- Community
- End user
- Events
- Opinion
- Featured
- Data on Kubernetes Report
- DoK Days
- DoK Day at KubeCon EU 2024
- DoK Day at KubeCon NA 2022
Feb 22, 2022
DBAs need lovin' too!
An honest discussion about the challenges of running stateful, distributed applications inside of Kubernetes. This talk features Umair Mufti, former Manager of Data Services at DreamWorks where he led the development of a Kubernetes-based, Database-as-a-Service platform. Currently building products for Portworx that incorporate all the lessons learned from managing enterprise-grade databases on Kubernetes.
Feb 15, 2022
CFP DoK Day EU 2022
We are back at it again! As Kubecon Europe 2022 is quickly approaching, we are looking for speakers who can share their knowledge about the art of running stateful workloads on Kubernetes. Happening on Monday, May 16, from 9:00 AM - 5:00 PM CET, the event will be 100% virtual and will feature speakers from all over the world.
Feb 15, 2022
Scheduled Scaling with Dask and Argo workflows
Complex computational workloads in Python are a common sight these days, especially in the context of processing large and complex datasets. Battle-hardened modules such as Numpy, Pandas, and Scikit-Learn can perform low-level tasks, while tools like Dask make it easy to parallelize these workloads across distributed computational environments.
Feb 10, 2022
Announcing DoK London!
DoKC is coming to London! Our community is international, and we have been operating fully online. As the community is growing and running stateful workload on Kubernetes is on its way to becoming an industry-standards, we are increasing our impact by launching local chapters with in-person events, starting with London!
Feb 8, 2022
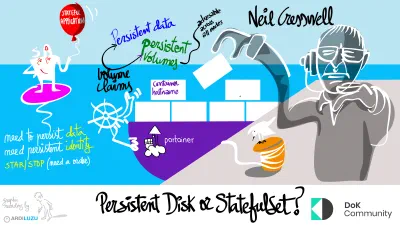
Persistent Disk or StatefulSet?
There is confusion amongst Kubernetes users as to when one should make a Deployment with a PVC and when they should use a StatefulSet with a PVC. There is also a general lack of understanding when it comes to disk access policies, what RWO/RWX means, and what they allow you to do. These concepts are complicated and require a deep level of understanding in order to avoid users making bad decisions that they come to regret later.
Feb 1, 2022
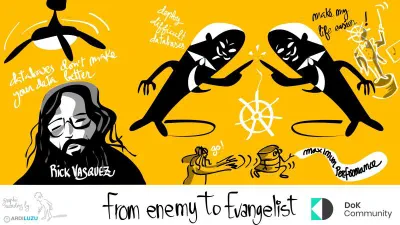
From Enemy to Evangelist of Stateful Workloads on Kubernetes
Kubernetes was originally designed to run stateless workloads. Today, it is increasingly used to run databases and other stateful workloads. Rick Vasquez used to be a huge opponent of putting any data in Kubernetes, now he is one of the most vocal proponents of doing so. Learn why he changed his mind.
Jan 30, 2022
Deploying Enterprise Databases on Kubernetes
“Is Kubernetes ready for stateful workloads?” is the first question that pops up when decision-makers consider deploying databases on Kubernetes. For years the answer was “don’t do it”, and for good reasons. Kubernetes was initially designed to handle the orchestration of stateless workload. But the technology has matured, and it is time to reconsider running data on Kubernetes.
Jan 24, 2022
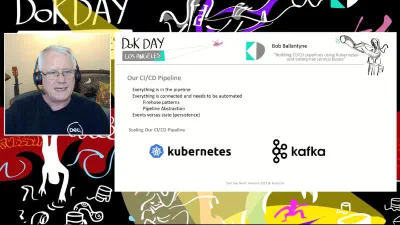
Building CI/CD Pipelines Using Kubernetes
According to Bob Ballantyne, traditional CI/CD pipelines are not suitable for native Kubernetes. K8s brings lots of desired features for the enterprise, however, migrations from static virtual machines bring lots of new challenges.
Jan 20, 2022
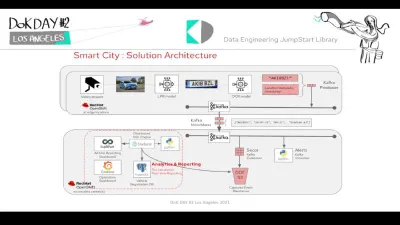
Smart Cities data infrastructure in a cloud-native containerized environment
Smart Cities represent complex and challenging environments that generate an overwhelming amount of data to ingest, transfer, prepare and store. In this presentation – which is based on a fictitious but potential real world scenario in the city of London – we will see how you can leverage different data engineering patterns to create a fully automated edge-to-core data pipeline for interesting use cases which include license plate recognition and facial recognition.
Jan 14, 2022
Machine learning on Kubernetes with Metaflow
Metaflow is an open source machine learning platform, originally built and broadly battle-tested at Netflix to help with ML, analytics, and other data-intensive use cases. It was initially built to heavily rely on AWS, but it’s been rebuilt to run large-scale data crunching workloads on Kubernetes. In this talk, Oleg shares the surprises and challenges they’ve run into in our journey to get to a consistent, friendly experience on Kubernetes for data scientists.
Jan 6, 2022
How to deploy Elasticsearch on Kubernetes
99.co is Singapore’s fastest-growing real estate portal. We power our listings search feature with Elasticsearch (ES), a distributed search engine that can perform complicated search queries at a fast speed. Our backend is a microservices architecture running in Google Kubernetes Engine (GKE), which includes the search service.
Dec 20, 2021
DoKC 2021 year in review
As 2021 is coming to an end, we wanted to take a step back to appreciate what the Data on Kubernetes Community achieved. Spoiler alert: a lot! The DoKC organized not one Dok Day, but two! For KubeCon EU and KubeCon NA, we learned a ton from our community. If you were not able to attend, fear not! You can access all the talks here (EU) and here (NA). Our Dok Days include music interludes, an excellent way to relax in between talks!